Cenkay YamanOct 09, 20268 min
Migrating Open WebUI from SQLite to PostgreSQL: Field Notes from Kubernetes
Moving Open WebUI from SQLite to PostgreSQL can be done with no data loss and only a few minutes of downtime. This post walks through the process on a Kubernetes deployment, the problems you’re…
llmpostgresqlopen-webuillm-agentdata-migration
Read article ↗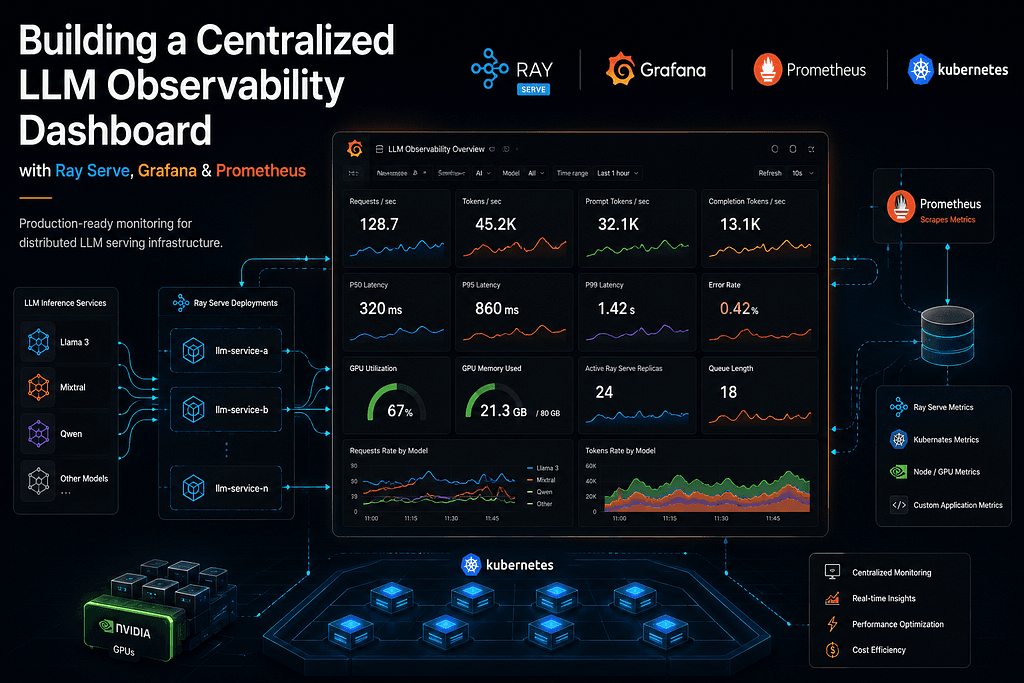
Cenkay YamanJul 28, 20263 min
Observability for LLMs on Ray Cluster: A Centralized Grafana Dashboard Hub
Ray's dashboard shows cluster health, but not the latency of the model being served. The post brings time to first token, token rate, KV cache utilization, and Ray Serve replica counts into one Grafana dashboard. It also explains why panels stay empty when Prometheus labels do not match.
kubernetesaillmraysnvidia
Read article ↗
Cenkay YamanMay 20, 20267 min
Slicing an NVIDIA GPU with MIG and Shipping It to Kubernetes for vLLM Inference
Kubernetes gives a pod the whole GPU by default. The post partitions the card into isolated MIG slices, runs the device plugin in mixed mode, and schedules vLLM workloads on those slices. Capacity is calculated per slice because MIG slice memory is not pooled.
vllmhugging-facellmmigkubernetes
Read article ↗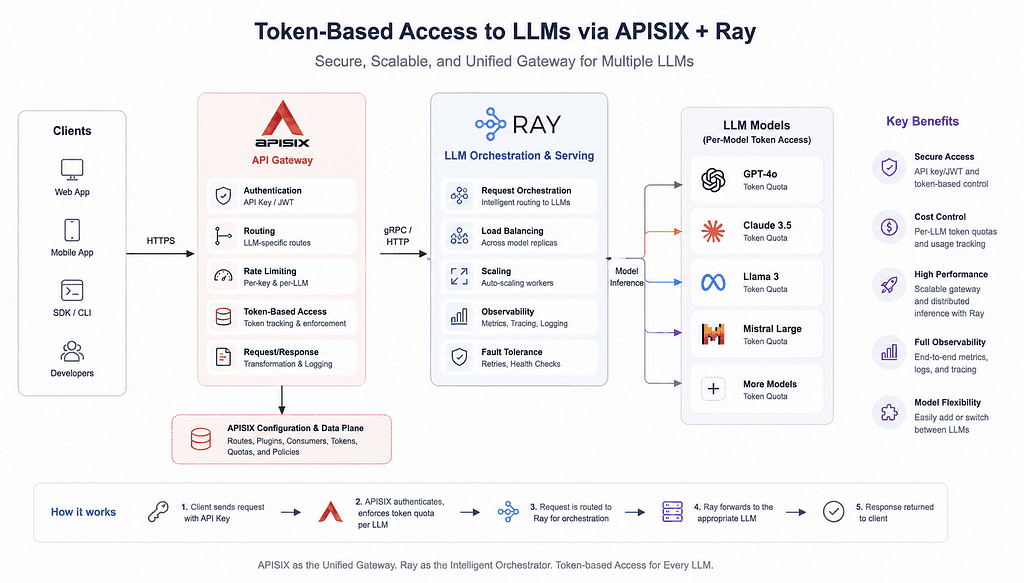
Cenkay YamanMay 06, 202612 min
Per-Model Token Authentication for LLMs on Ray Serve and vLLM with APISIX
The post places Apache APISIX behind Nginx so teams can reach only the models they are allowed to use. `key-auth` validates the token and `consumer-restriction` checks access to the route. It also covers buffering that breaks streaming, timeouts across the request path, and plugins missing from Helm values.
kuberayapache-apisixnvidiallmkubernetes
Read article ↗
Cenkay YamanApr 16, 202610 min
Solving the “In Use by Another Client” Error on NVIDIA H200 NVL GPUs: A Step-by-Step…
MIG cannot be enabled on an H200 NVL node, GPU reset returns "In use by another client", and `nvidia-smi` shows no process. The card is held by the kernel framebuffer created during boot. The post explains the use of `nomodeset` on headless GPU nodes and the diagnostic steps that led there.
gpunvidianvidia-h200error-handlingai
Read article ↗
Cenkay YamanApr 03, 20266 min
Migrating Label Studio Storage: From Local Files to S3 on Kubernetes
Label Studio stores file paths in each task's JSON, so changing storage breaks existing tasks. The post uses two scripts against the Label Studio API to rewrite paths in bulk and move tasks to S3. It also covers matching S3 keys to relative paths, presign settings for internal S3, proxy variables, and ReadWriteOnce volume constraints.
kubernetesmigrationairgappeddata-migrationlabel-studio
Read article ↗
Cenkay YamanMar 22, 20264 min
Kubeflow on RKE2 Deployment & Troubleshooting Guide
Kubeflow pods report Running while the UI returns 504. RKE2 runs Nginx Ingress in `kube-system`, but the existing NetworkPolicies do not allow traffic from there into `istio-system`. The post identifies the missing rule and shows the NetworkPolicy that fixes it.
mlopskubeflowrancherllmkubernetes
Read article ↗
Cenkay YamanMar 12, 202611 min
Running Notebook Pipelines on Kubernetes from Airflow — Out-of-Cluster with KPO
Airflow can run on a separate server while notebook jobs run in Kubernetes through KubernetesPodOperator. The post sets up a namespace-scoped ServiceAccount, a kubeconfig generated from it, Python base images, and a DAG that removes the pod after the job. It also notes that long-lived ServiceAccount tokens need regular rotation.
automationapache-airflowkubernetesairflowcontainers
Read article ↗
Cenkay YamanMar 08, 202613 min
NVIDIA H200 NVL USING ON RKE2 Kubernetes WITH MIG:
The post adds an H200 NVL server to a bare-metal RKE2 cluster as a GPU node. It covers disabling nouveau, selecting the NVIDIA data-center driver, using RKE2's containerd template, and configuring MIG profiles for multi-tenant scheduling. It also documents RKE2-specific details missing from generic Kubernetes guides.
cudagpukubernetesnvidianvidia-h200
Read article ↗
Cenkay YamanMar 05, 20267 min
Scale to Zero: Self-Hosted Azure DevOps Agents on Kubernetes with KEDA
The post connects KEDA to an Azure DevOps queue so self-hosted agent pods start when work arrives and scale to zero when idle. Each runtime pool scales independently in the Helm chart, and capability tags route jobs to the right pool. It also explains the behavior difference between ScaledObject and ScaledJob.
Read article ↗
Cenkay YamanMar 01, 20269 min
Monitoring Ray on Kubernetes with kube-prometheus-stack
A step-by-step guide to wiring Prometheus, Grafana, PodMonitor, and ServiceMonitor into your KubeRay cluster — so you finally see what’s…
Read article ↗
Cenkay YamanFeb 22, 202614 min
Ray Fault Tolerance on Kubernetes: GCS, Workers, and HA Redis Sentinel
What happens when your head node crashes mid-job — and how to make sure your workers keep running. A practical guide to GCS fault tolerance…
Read article ↗Cenkay YamanFeb 19, 20266 min
Serving Multiple LLMs with Fractional GPU on Ray Cluster
In the first part of this series, we built a production-grade Ray Cluster using KubeRay. The cluster was healthy, scalable, and ready — but…
Read article ↗Cenkay YamanFeb 18, 20269 min
Running Ray on Kubernetes: A Production Setup Guide
Helm-based installation, custom GPU images, NFS model storage, and Prometheus/Grafana observability on a real production cluster.
Read article ↗